Back to Blog

Tagged

knowledge-management
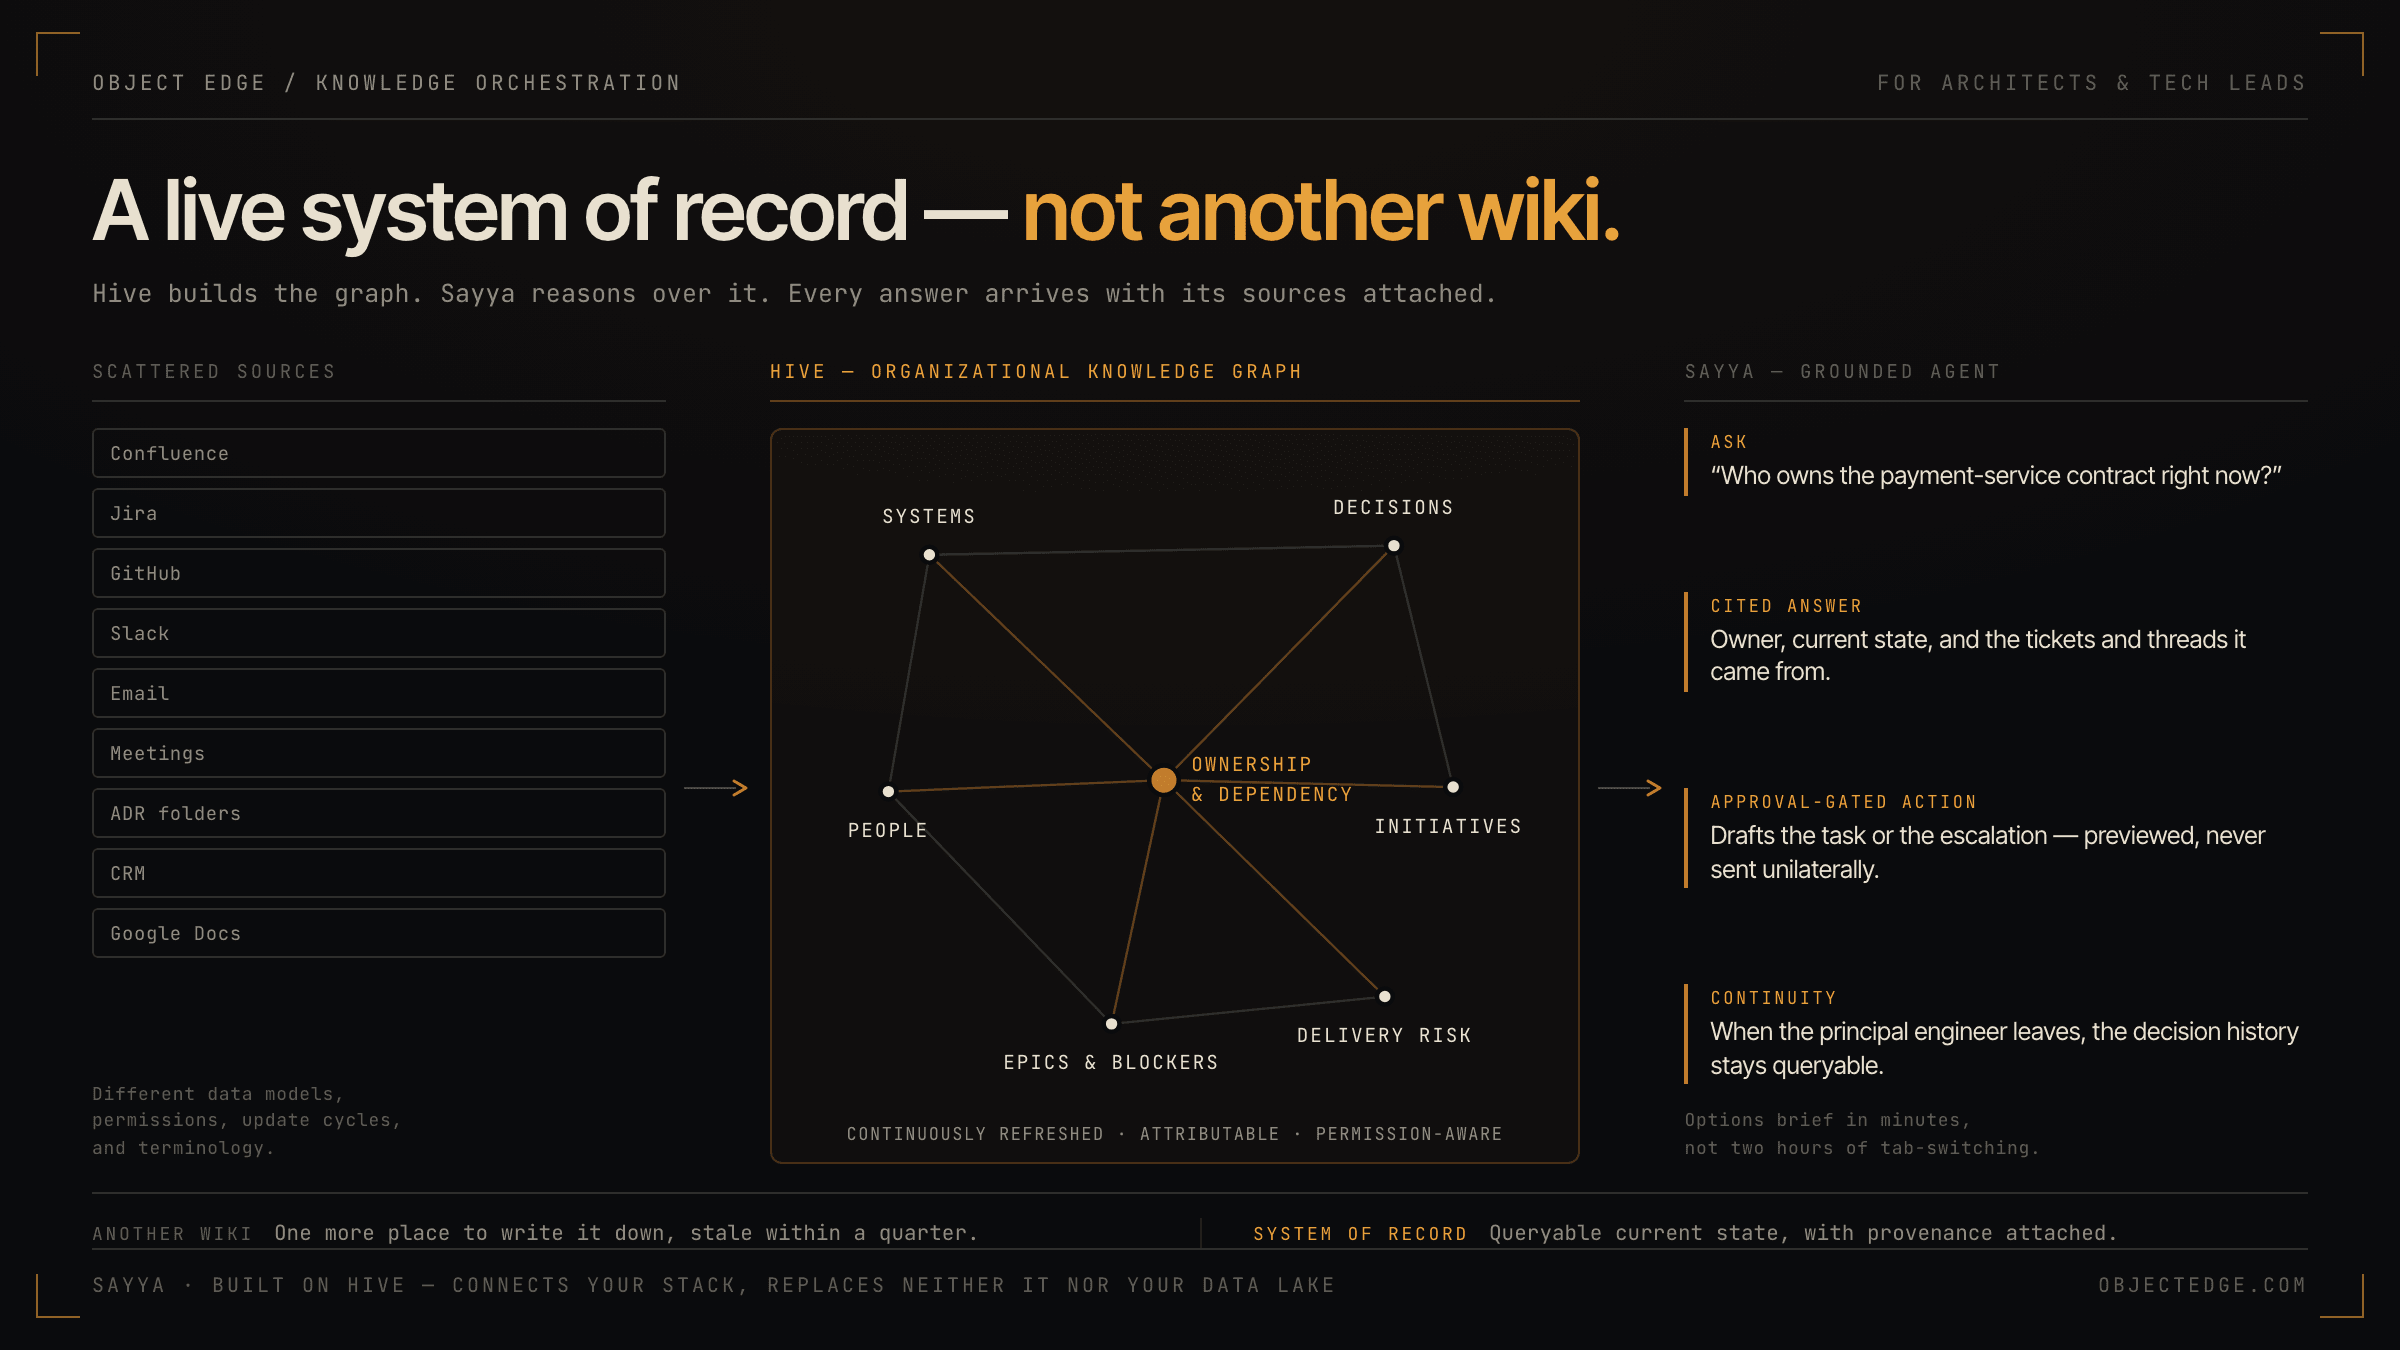

Diagram titled 'A live system of record — not another wiki' showing a three-stage flow. On the left, scattered sources — Confluence, Jira, GitHub, Slack, email, meetings, ADR folders, CRM and Google Docs — each with different data models, permissions, update cycles and terminology. An arrow leads to the centre: Hive, an organizational knowledge graph drawn as a node-link diagram whose hub is ownership and dependency, linked to systems, decisions, people, initiatives, epics and blockers, and delivery risk; the panel is labelled continuously refreshed, attributable, permission-aware. A second arrow leads to Sayya, the grounded agent, which takes a question ('Who owns the payment-service contract right now?'), returns a cited answer with the tickets and threads it came from, stages approval-gated actions that are previewed and never sent unilaterally, and preserves continuity so decision history stays queryable when a principal engineer leaves. A footer contrasts another wiki — one more place to write it down, stale within a quarter — against a system of record with queryable current state and provenance attached

How Hive and Sayya give architects and tech leads a live system of record—not another wiki

Hive builds a continuously refreshed organizational knowledge graph; Sayya is the grounded agent that queries it. Together they give solution architects and tech leads the decision context, dependency visibility, and controlled AI actions that scattered docs and tribal knowledge never could.
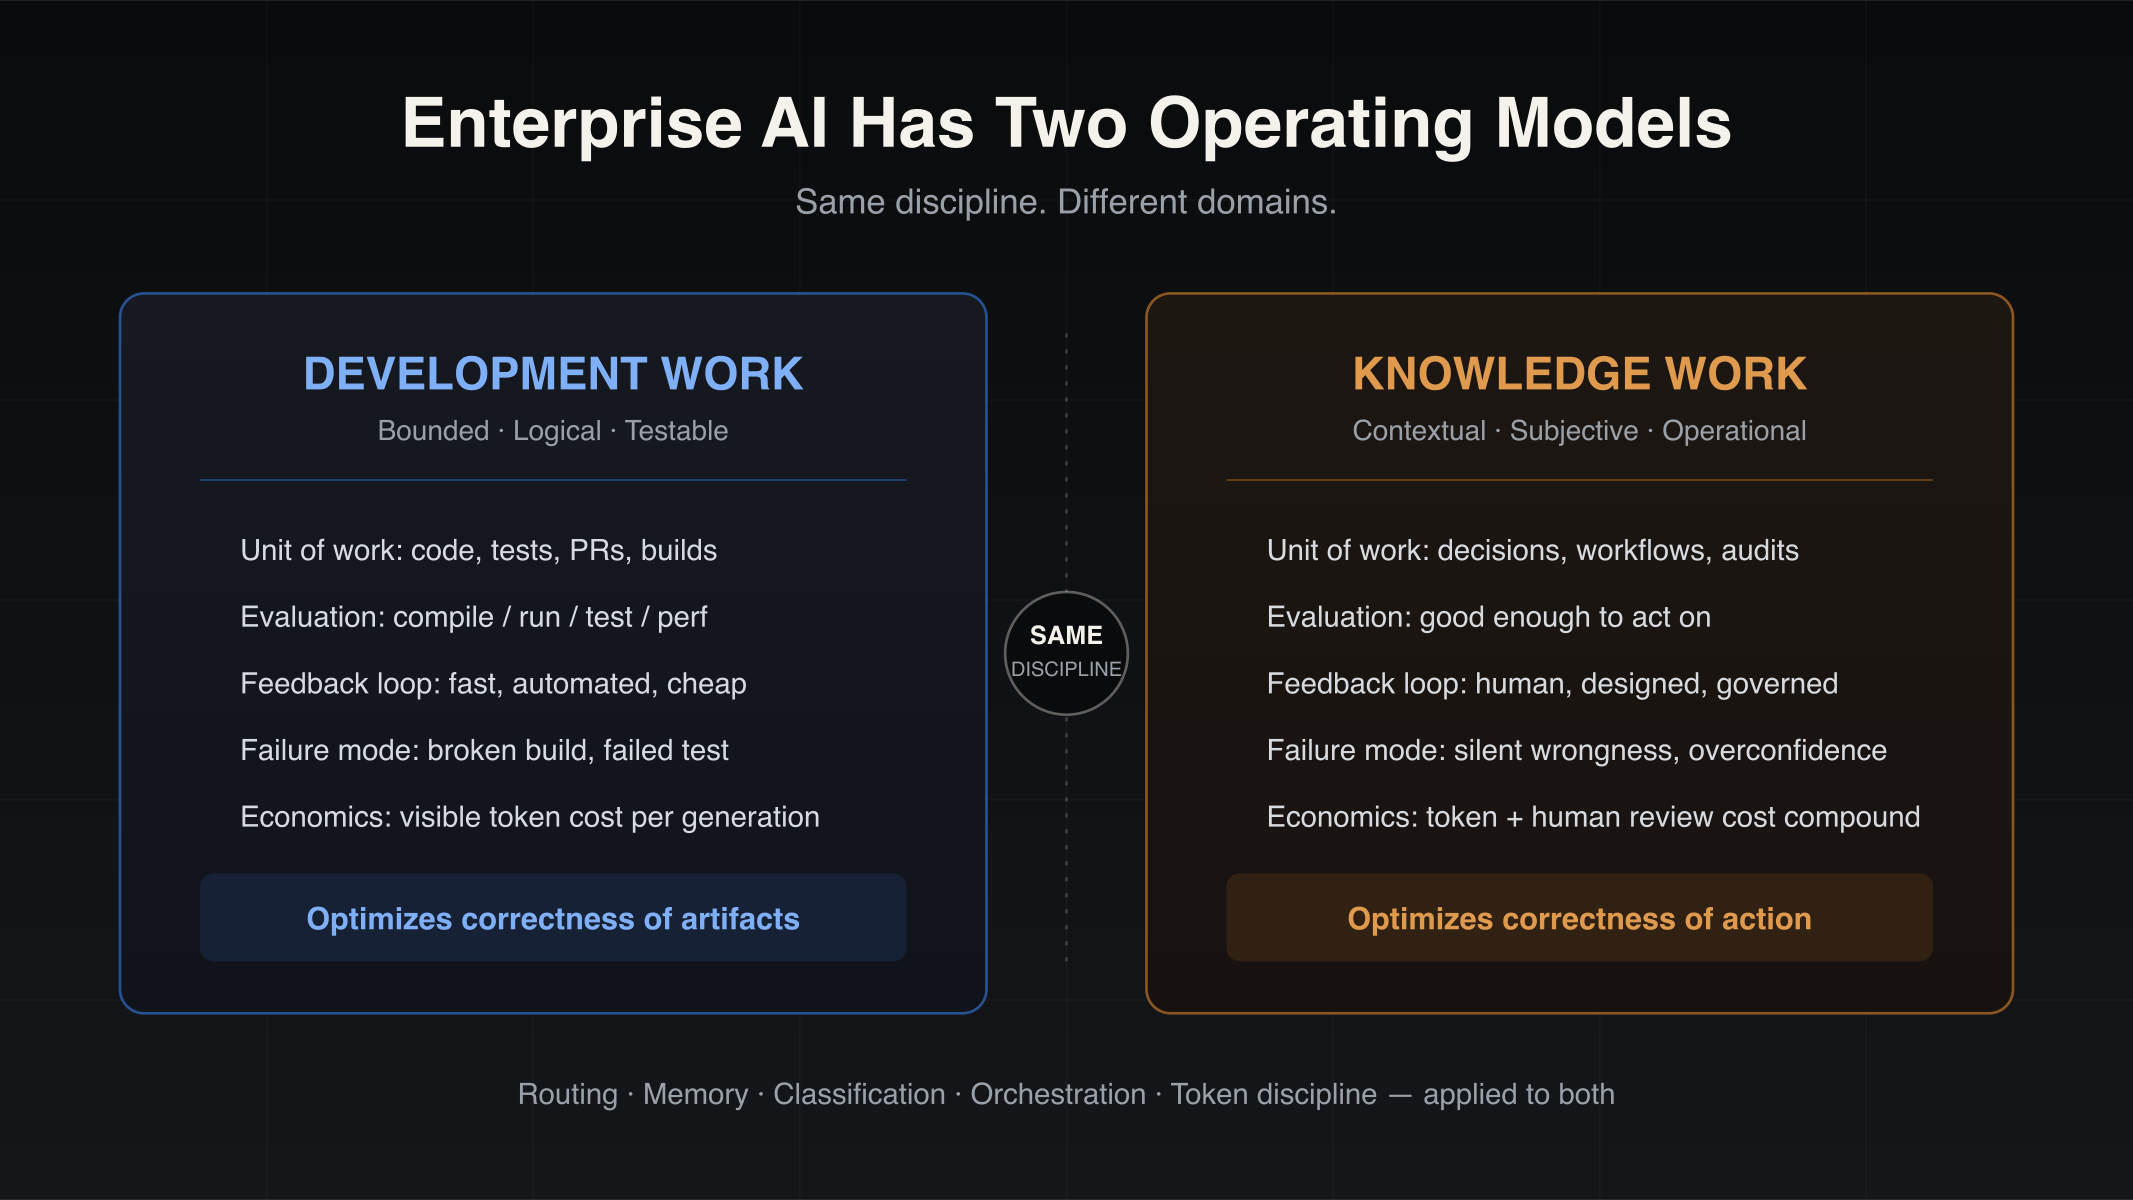
Diagram titled 'Enterprise AI Has Two Operating Models' comparing two panels: Development Work (bounded, logical, testable — code, tests, PRs, and builds evaluated by compile/run/test/perf with a fast automated feedback loop, optimizing correctness of artifacts) versus Knowledge Work (contextual, subjective, operational — decisions, workflows, and audits evaluated by 'good enough to act on' with a human, governed feedback loop, optimizing correctness of action), joined by a center badge reading 'Same Discipline' and a footer listing routing, memory, classification, orchestration, and token discipline as applied to both

Enterprise AI Has Two Operating Models: Development Work and Knowledge Work

Enterprise AI is splitting into two operating models — development work and knowledge work. Why coding-copilot playbooks stall on operational workflows, and which engineering disciplines transfer.
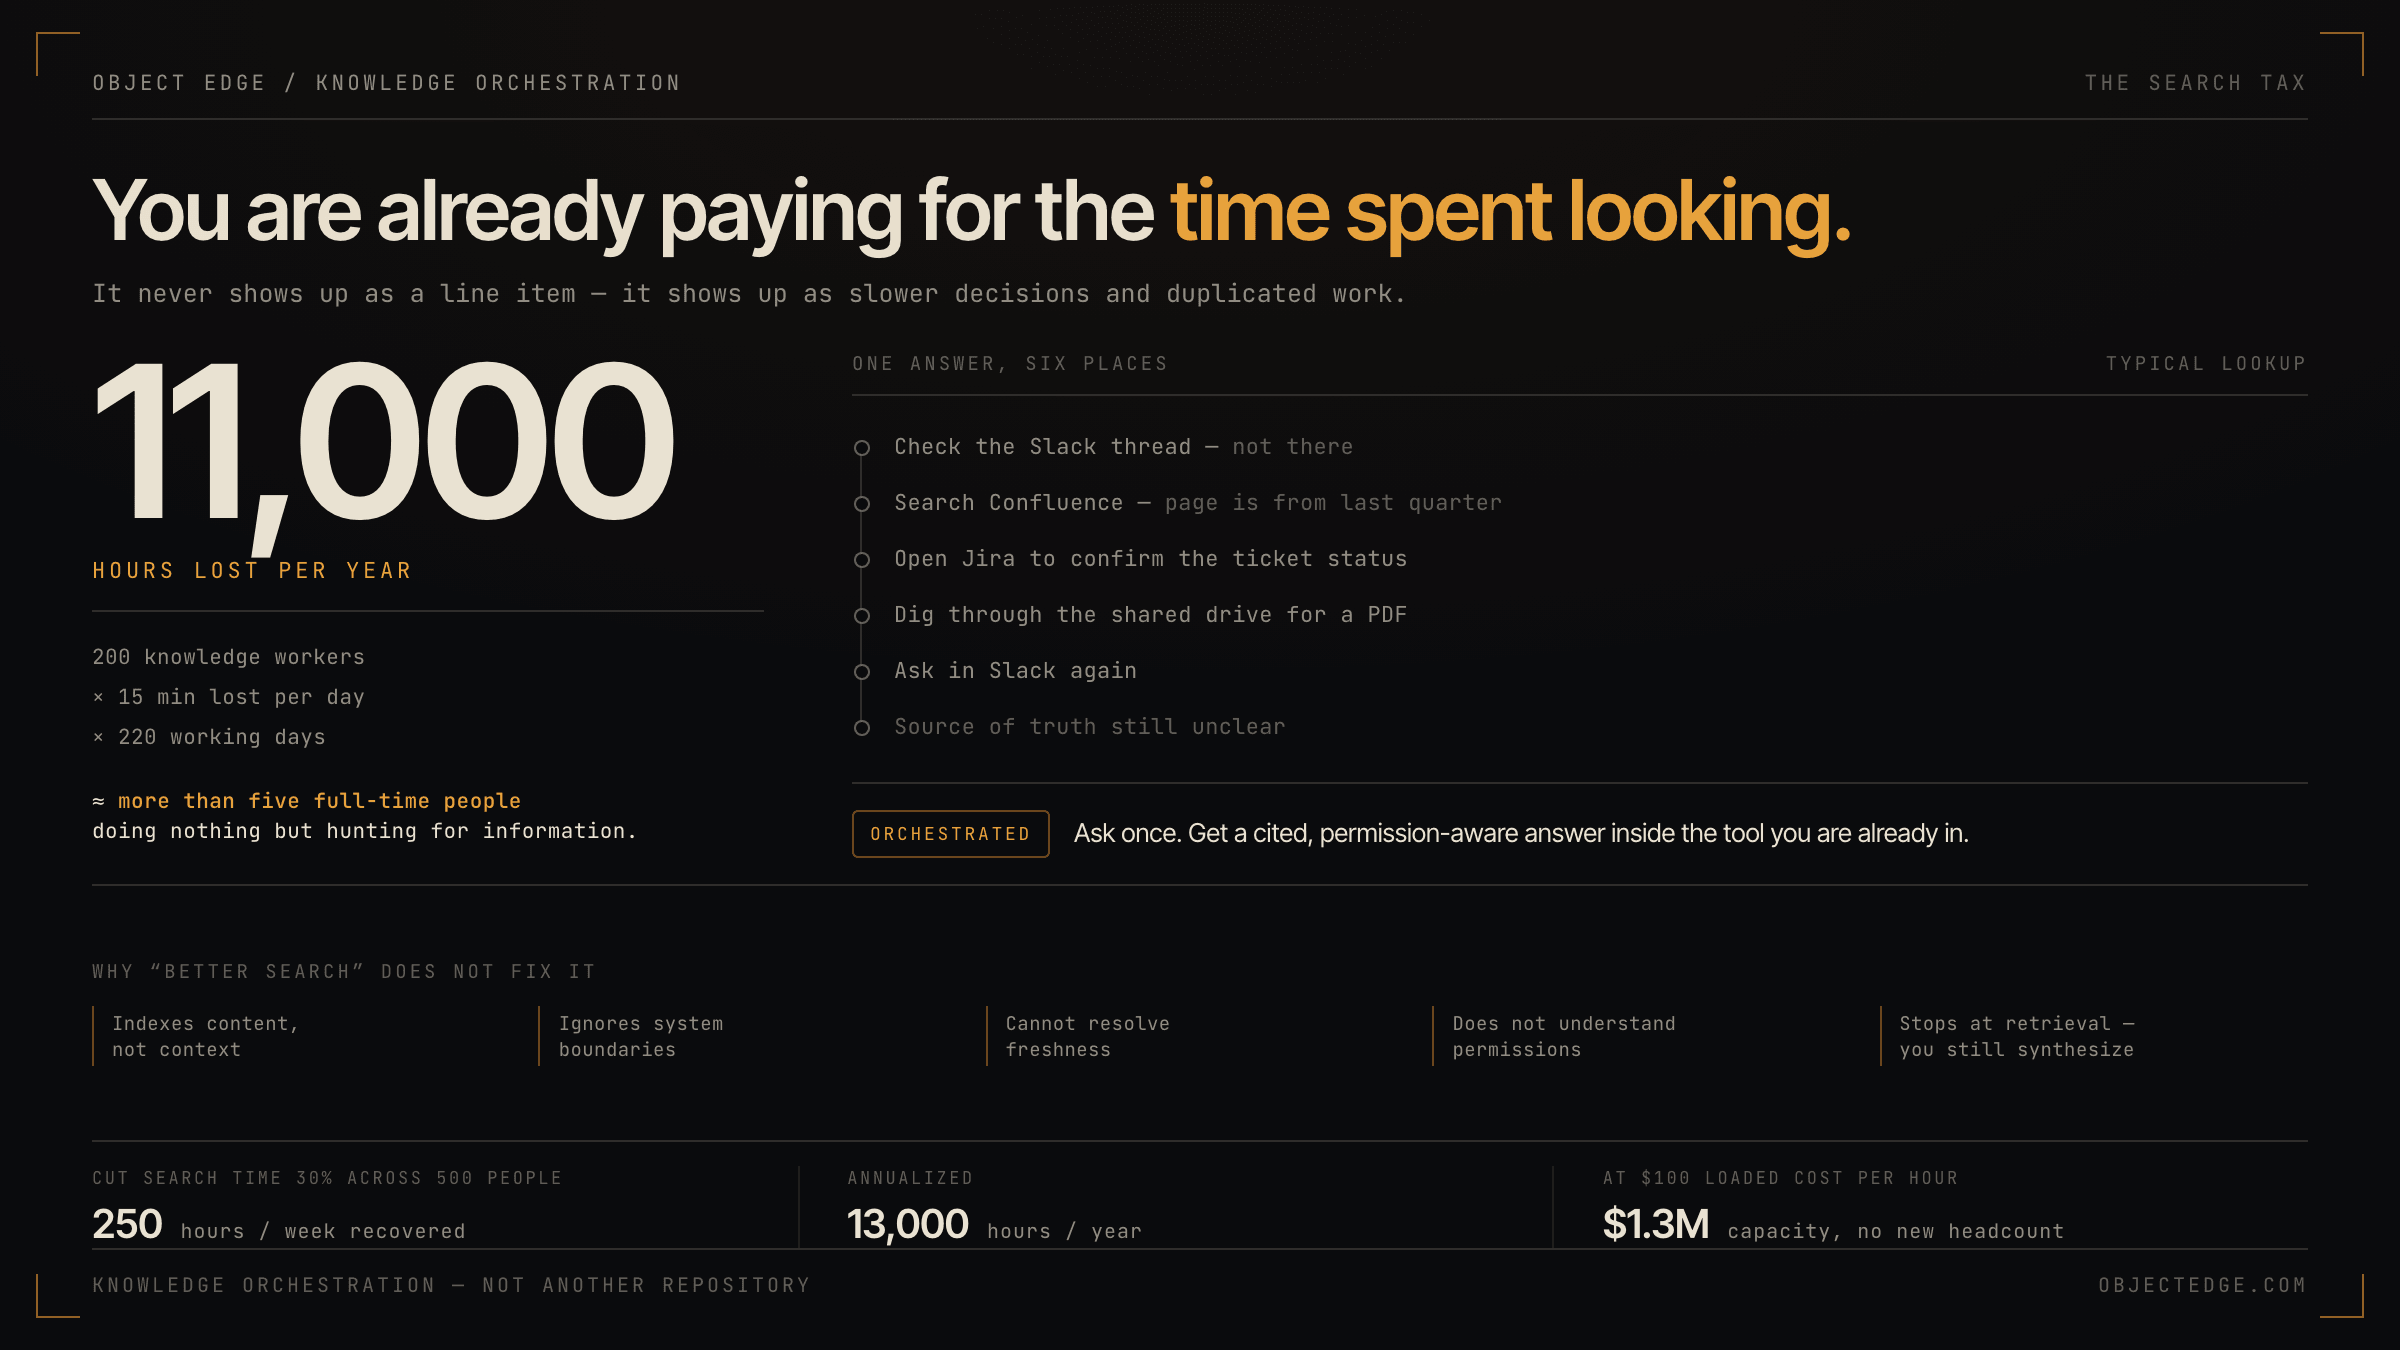
Diagram titled 'You are already paying for the time spent looking.' A hero figure of 11,000 hours lost per year is derived from 200 knowledge workers times 15 minutes lost per day times 220 working days — roughly more than five full-time people doing nothing but hunting for information. Beside it, a typical lookup is traced across six places: check the Slack thread (not there), search Confluence (page is from last quarter), open Jira to confirm ticket status, dig through the shared drive for a PDF, ask in Slack again, and still find the source of truth unclear; an orchestrated alternative asks once and returns a cited, permission-aware answer inside the tool the user is already in. A band explains why better search does not fix it — it indexes content not context, ignores system boundaries, cannot resolve freshness, does not understand permissions, and stops at retrieval. Three stat tiles show that cutting search time 30% across 500 people recovers 250 hours per week, 13,000 hours per year, or about $1.3M of capacity at $100 loaded cost per hour

Stop Losing Hours to Search: How Knowledge Orchestration Cuts Time Wasted Across Systems

Why teams burn hours hunting for answers across tools, and how knowledge orchestration reduces that friction for engineering and operations leaders.
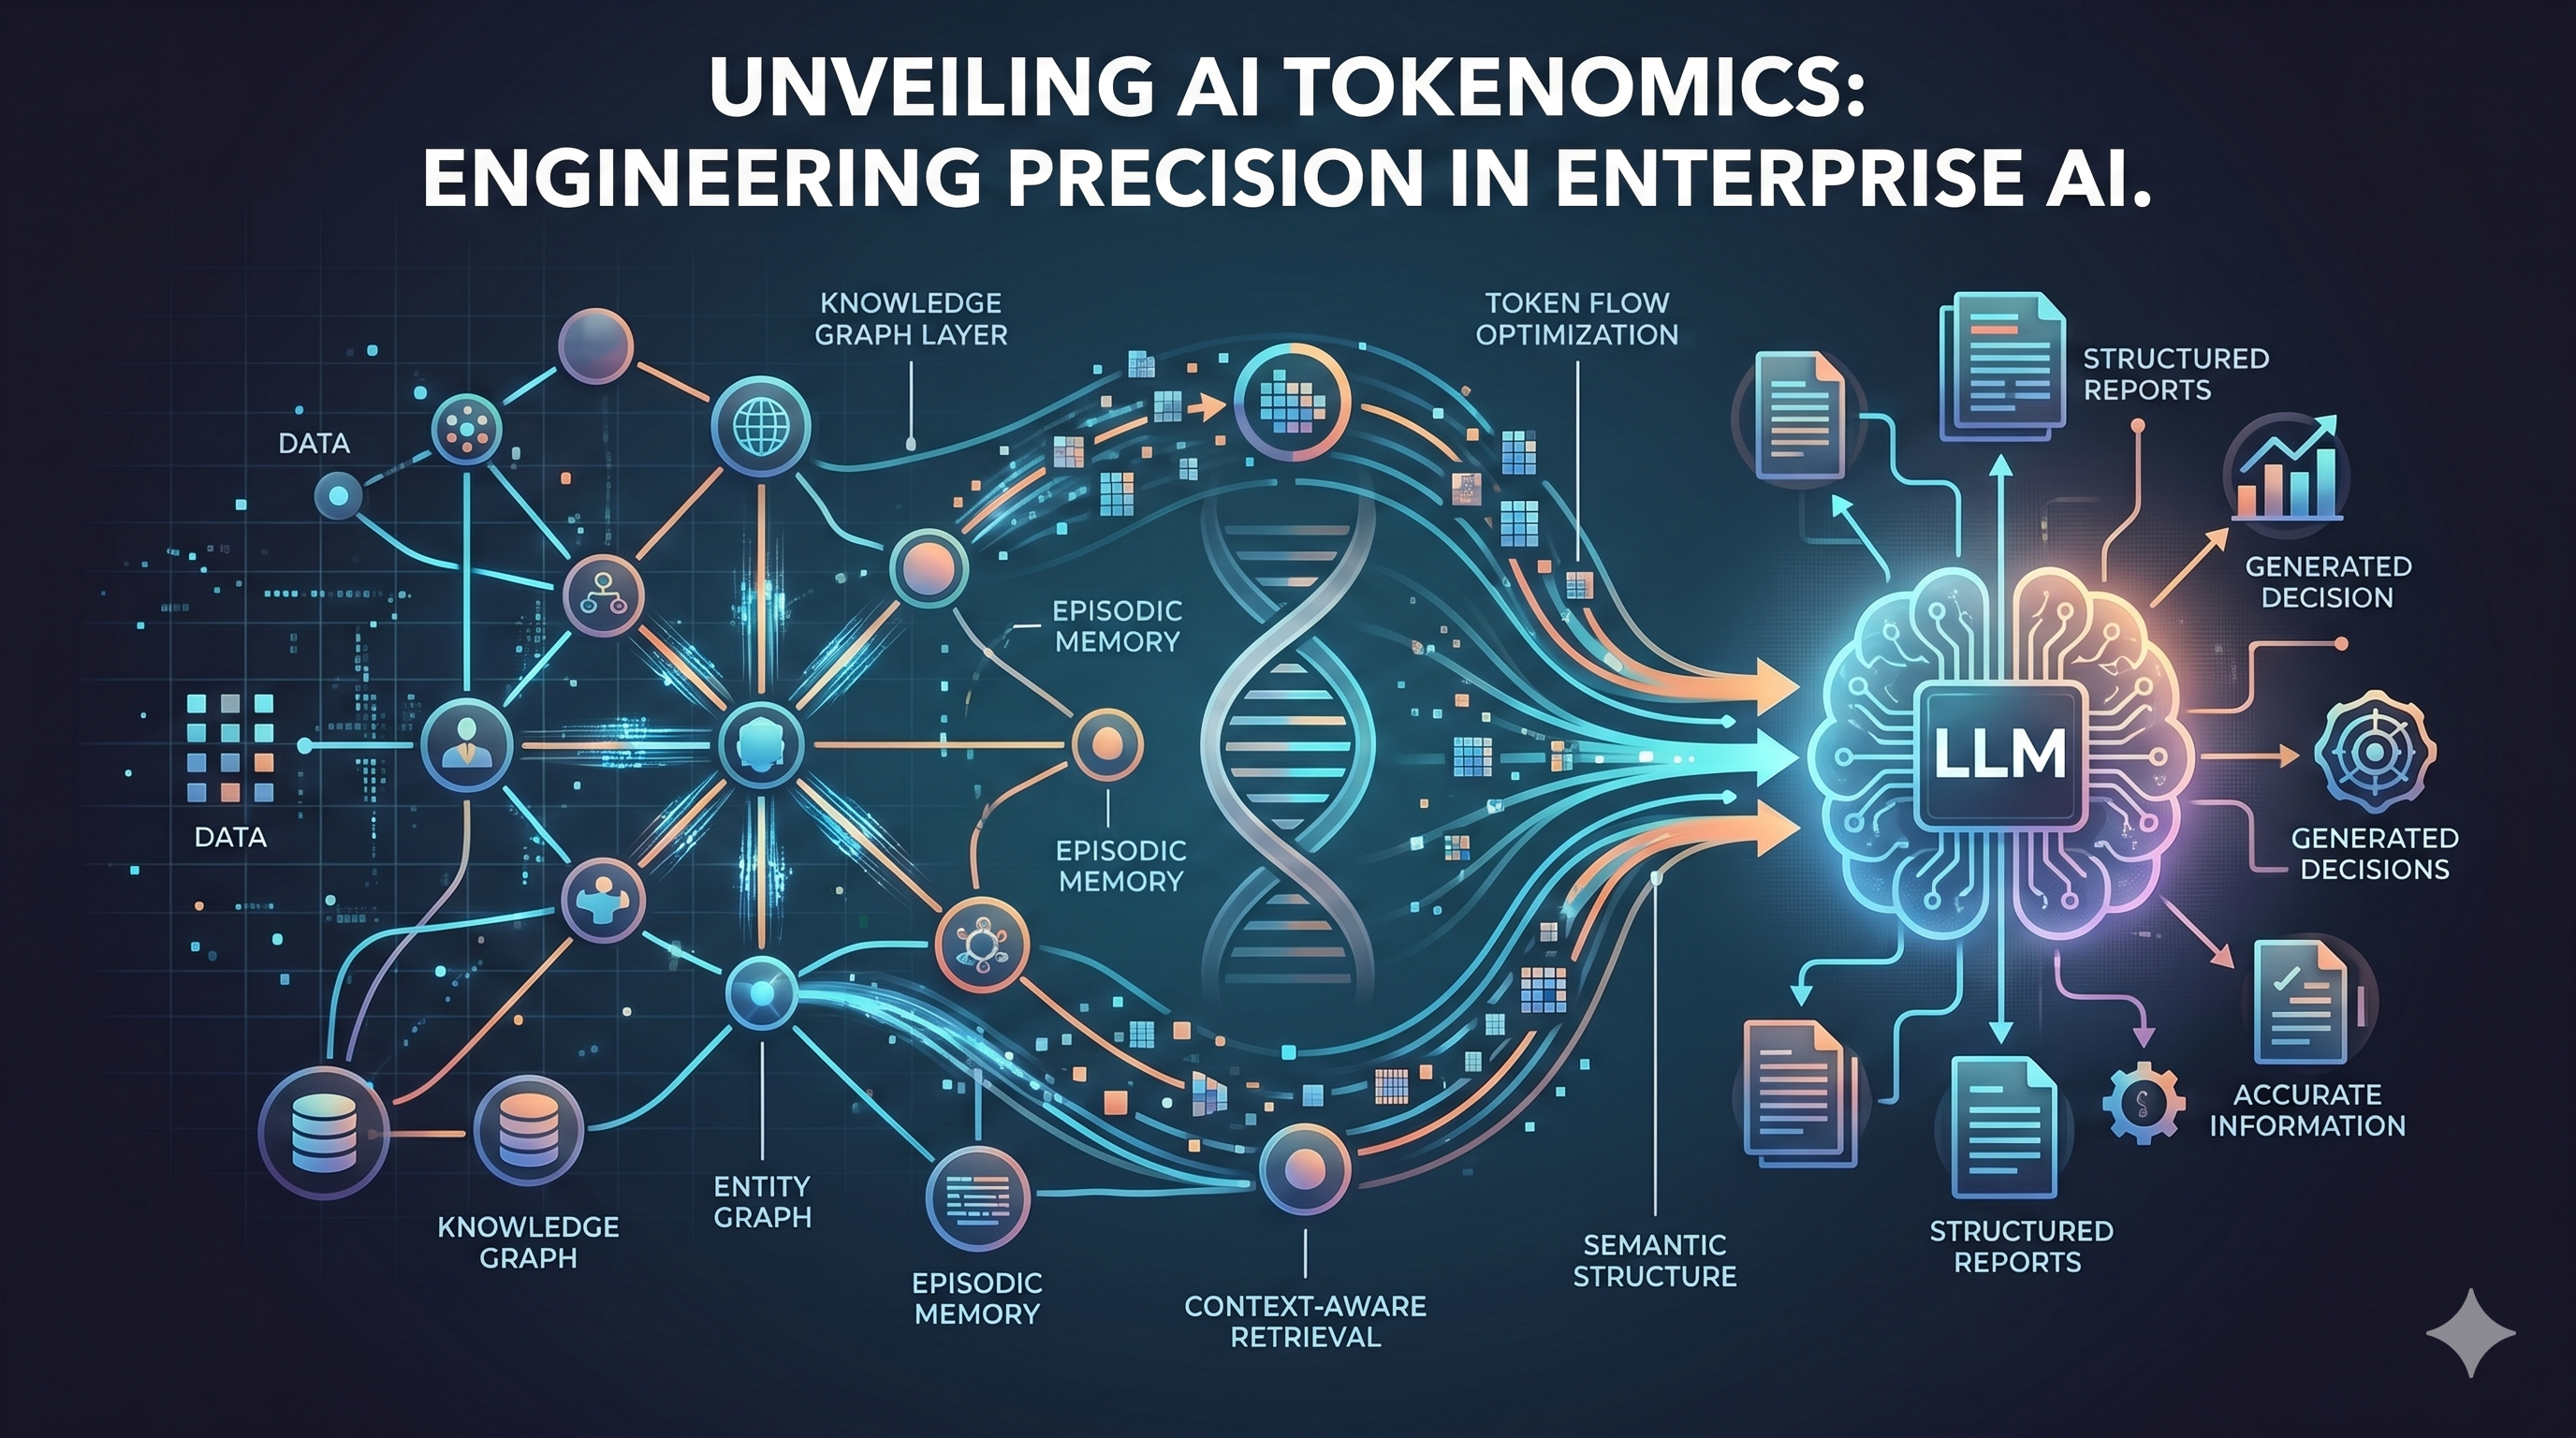
Diagram titled 'Unveiling AI Tokenomics: Engineering Precision in Enterprise AI' showing data sources flowing through a knowledge graph layer, entity graph, episodic memory, and context-aware retrieval into token-flow optimization and semantic structure, then into an LLM that produces structured reports, generated decisions, and accurate information

Tokenomics Is the New AI Efficiency Frontier — and Here's How We're Winning It

AI tokenomics is the discipline of managing token consumption at enterprise scale. Learn how semantic infrastructure, context-aware retrieval, and agent budgeting cut AI costs without sacrificing quality.
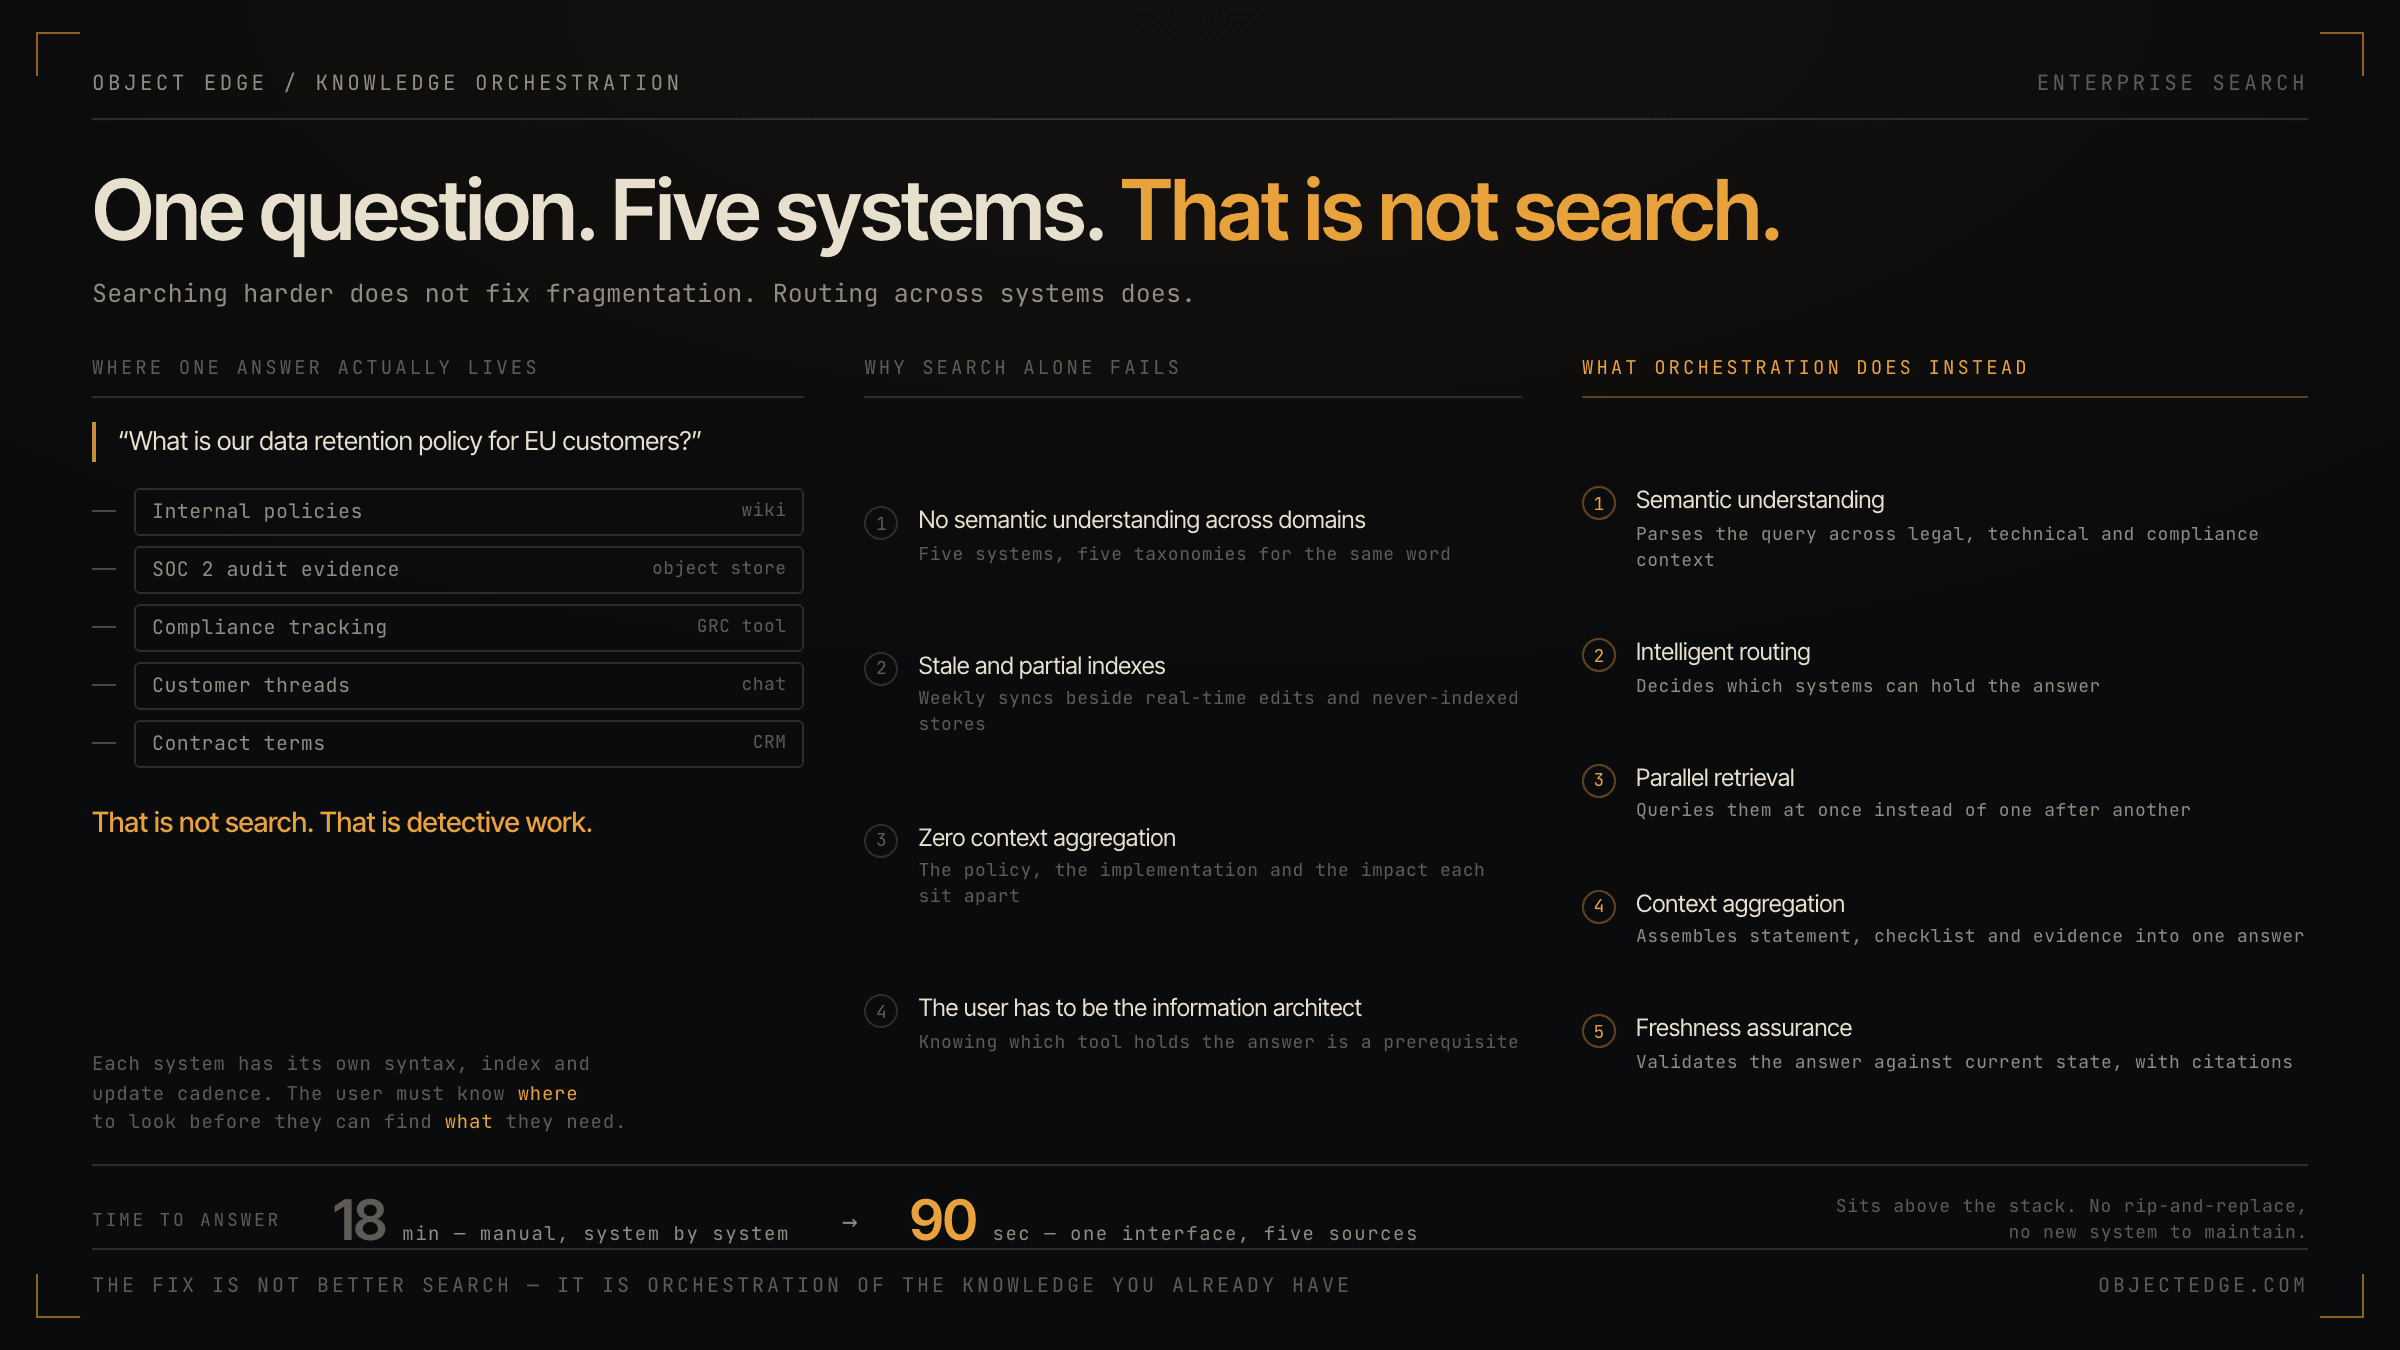
Diagram titled 'One question. Five systems. That is not search.' The left panel traces where a single answer actually lives — the question 'What is our data retention policy for EU customers?' resolves across internal policies in a wiki, SOC 2 audit evidence in an object store, compliance tracking in a GRC tool, customer threads in chat, and contract terms in the CRM — concluding that this is detective work, because each system has its own syntax, index and update cadence and the user must know where to look before they can find what they need. The middle panel lists four reasons search alone fails: no semantic understanding across domains, stale and partial indexes, zero context aggregation, and the user having to be the information architect. The right panel shows what orchestration does instead in five steps: semantic understanding, intelligent routing, parallel retrieval, context aggregation, and freshness assurance with citations. A footer compares time to answer — 18 minutes searching system by system against 90 seconds through one interface over five sources — and notes that the layer sits above the existing stack with no rip-and-replace

Why Knowledge Search Fails Inside Existing Tools — And What Actually Works

Most enterprise search tools waste 40% of user time. Here's why orchestration solves the real problem.
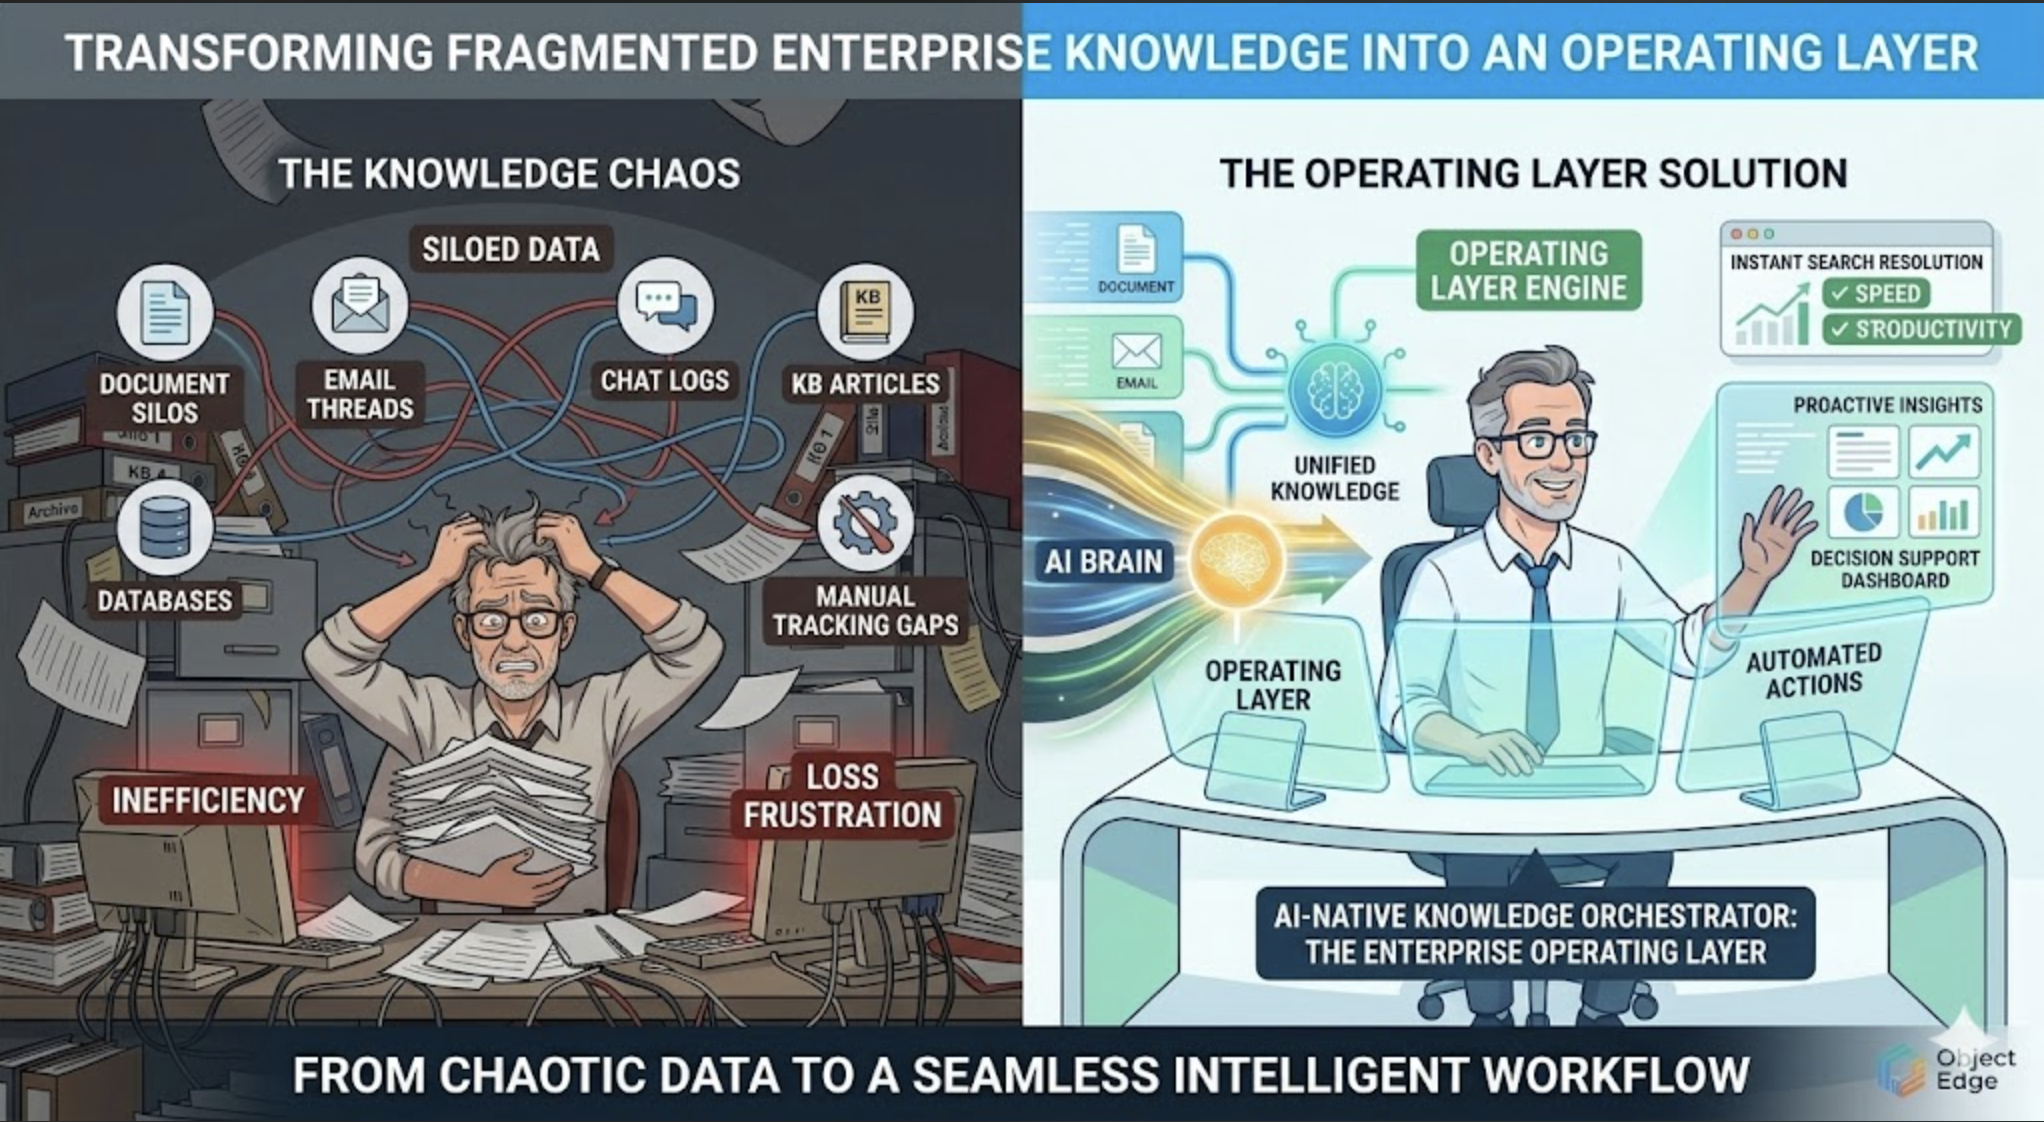
Transforming Fragmented Enterprise Knowledge Into an Operating Layer — left panel 'The Knowledge Chaos' shows a frustrated worker surrounded by document silos, email threads, chat logs, KB articles, and databases tangled in red and blue lines, with labels for siloed data, manual tracking gaps, inefficiency, and loss/frustration; right panel 'The Operating Layer Solution' shows a calm worker at a clean dashboard with an AI brain feeding into unified knowledge, instant search resolution (speed, productivity), proactive insights, decision support dashboard, and automated actions, captioned 'AI-Native Knowledge Orchestrator: The Enterprise Operating Layer — From Chaotic Data to a Seamless Intelligent Workflow'

Turn Fragmented Enterprise Knowledge Into an Operating Layer That Teams Can Actually Use

How enterprises unify scattered documents, systems, and tribal knowledge into a searchable, governed operating layer that improves speed, consistency, and decision-making.
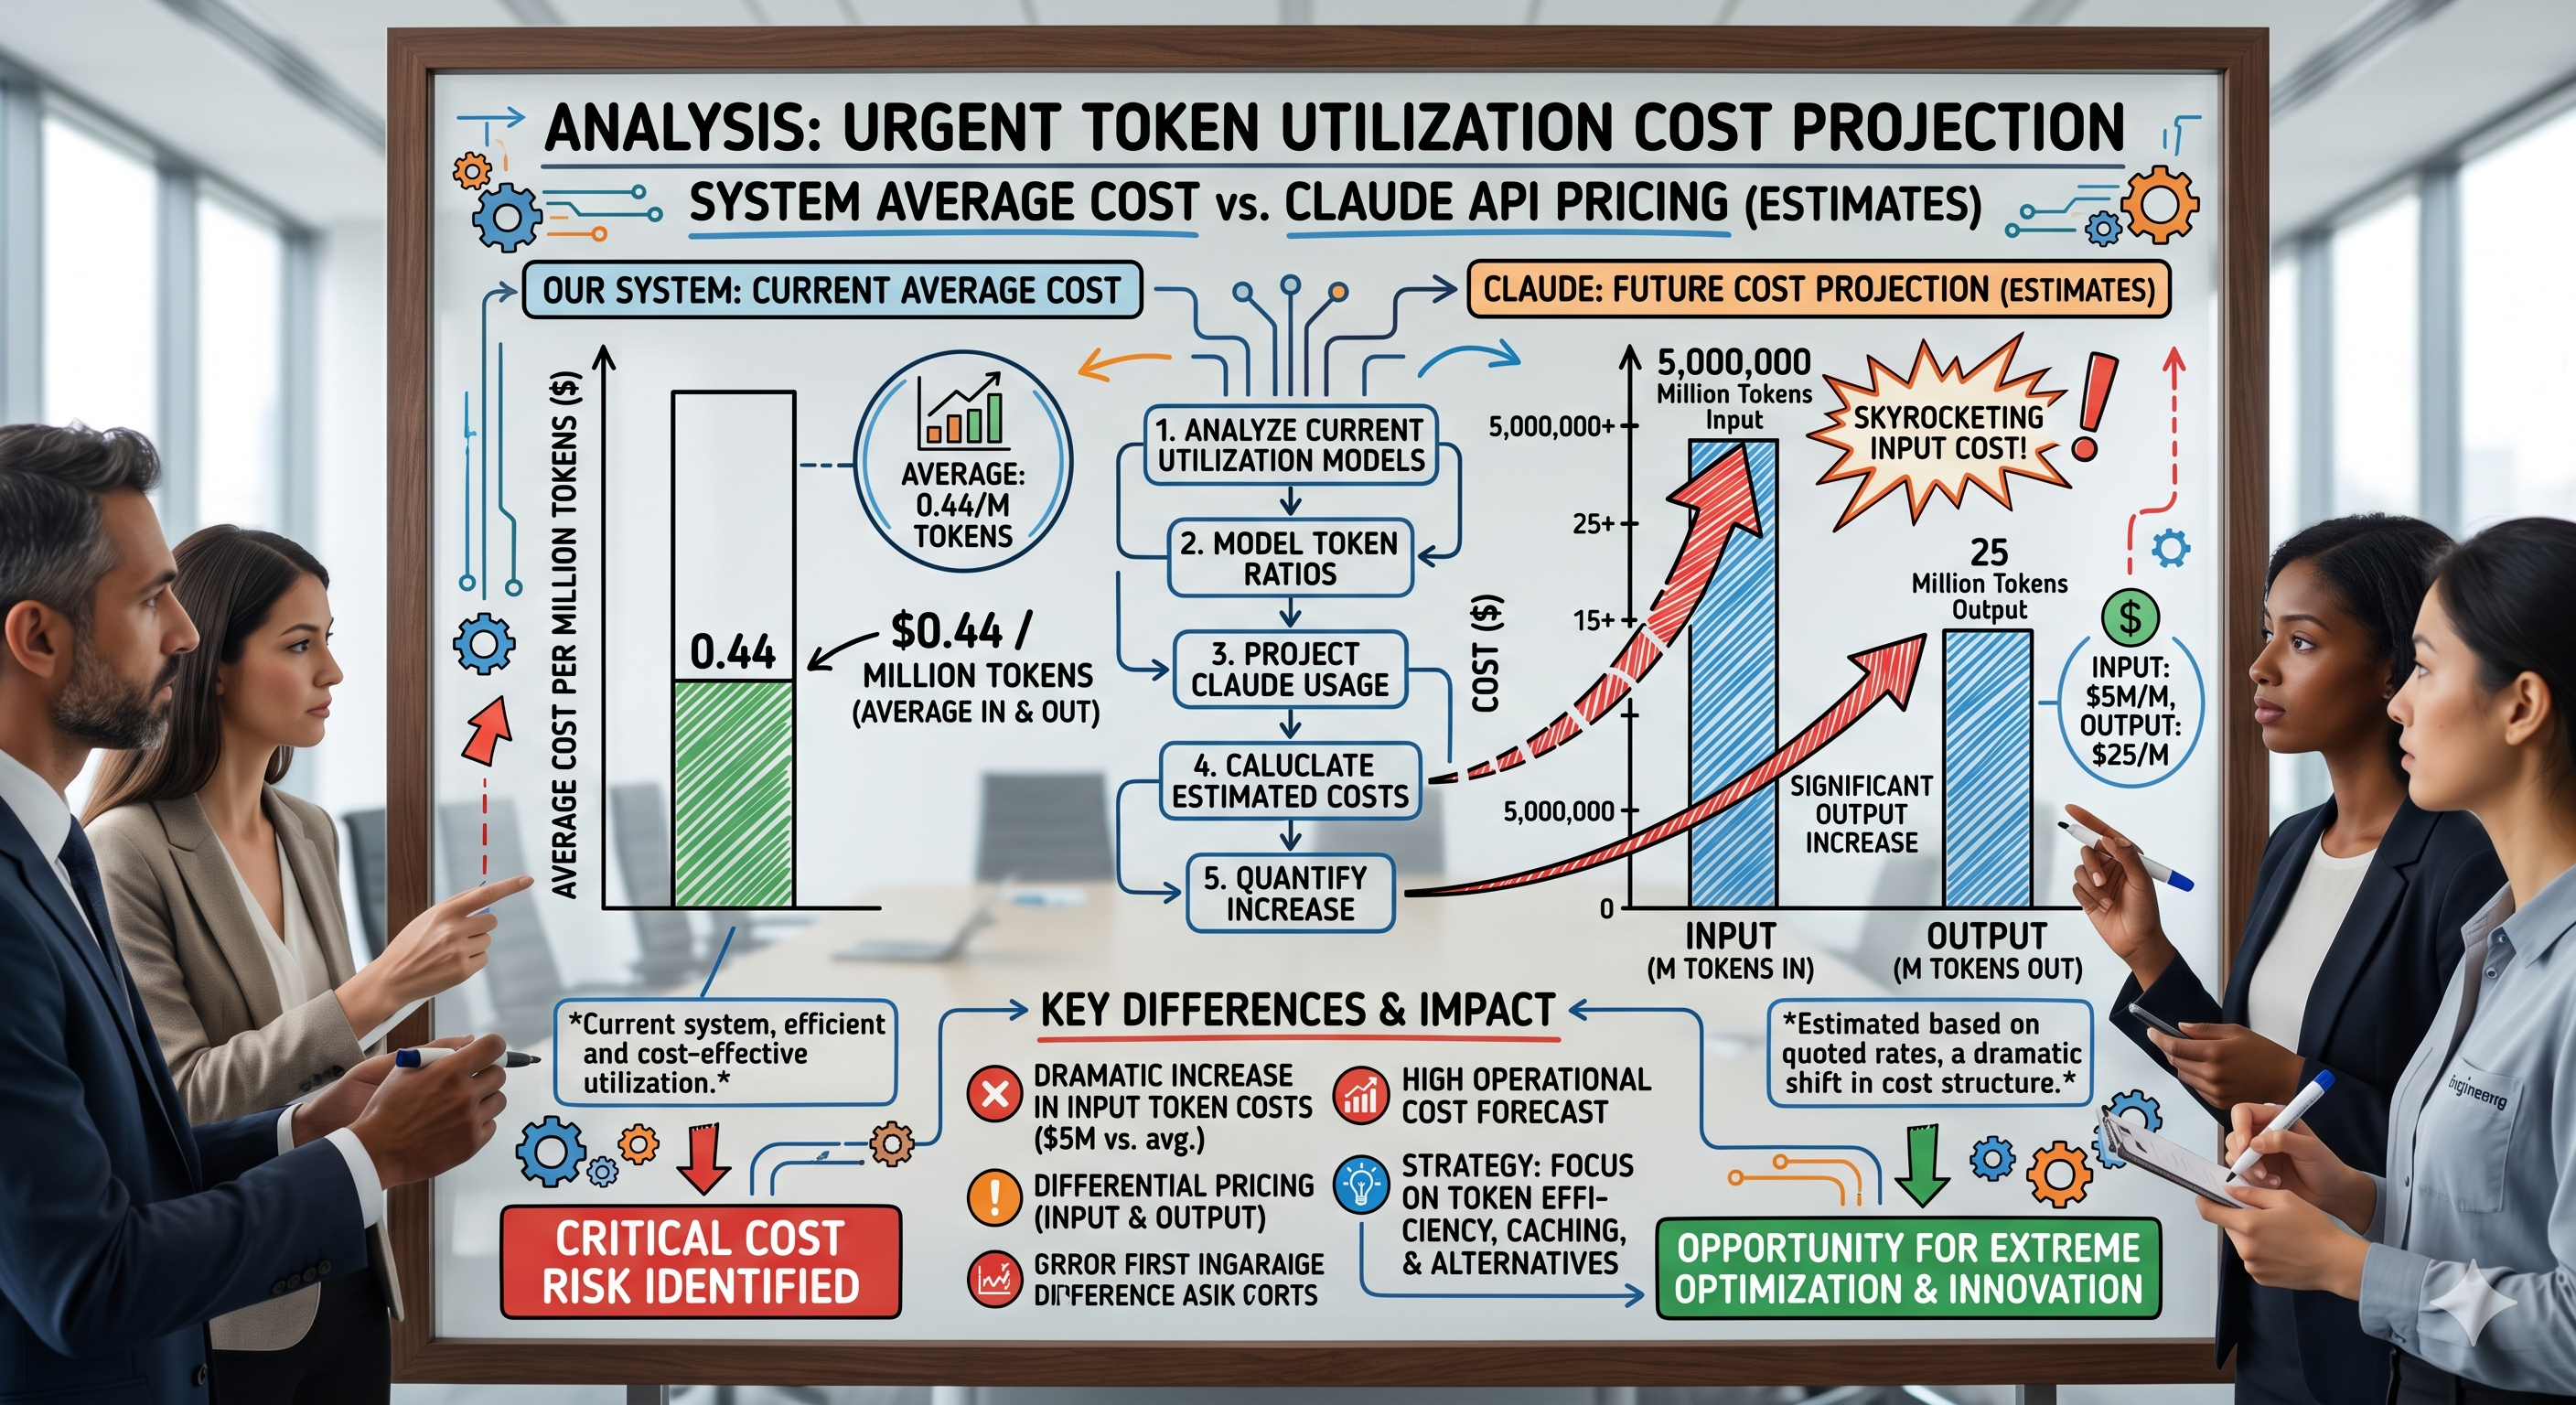
Whiteboard analysis of token utilization cost projections, comparing current system average cost per million tokens to future Claude API pricing estimates

The End of Subsidized Tokens Is Coming. Plan Accordingly.

The era of artificially cheap AI tokens is ending. Here is why token efficiency is becoming architecture, and how enterprises should plan a model portfolio strategy before prices spike.
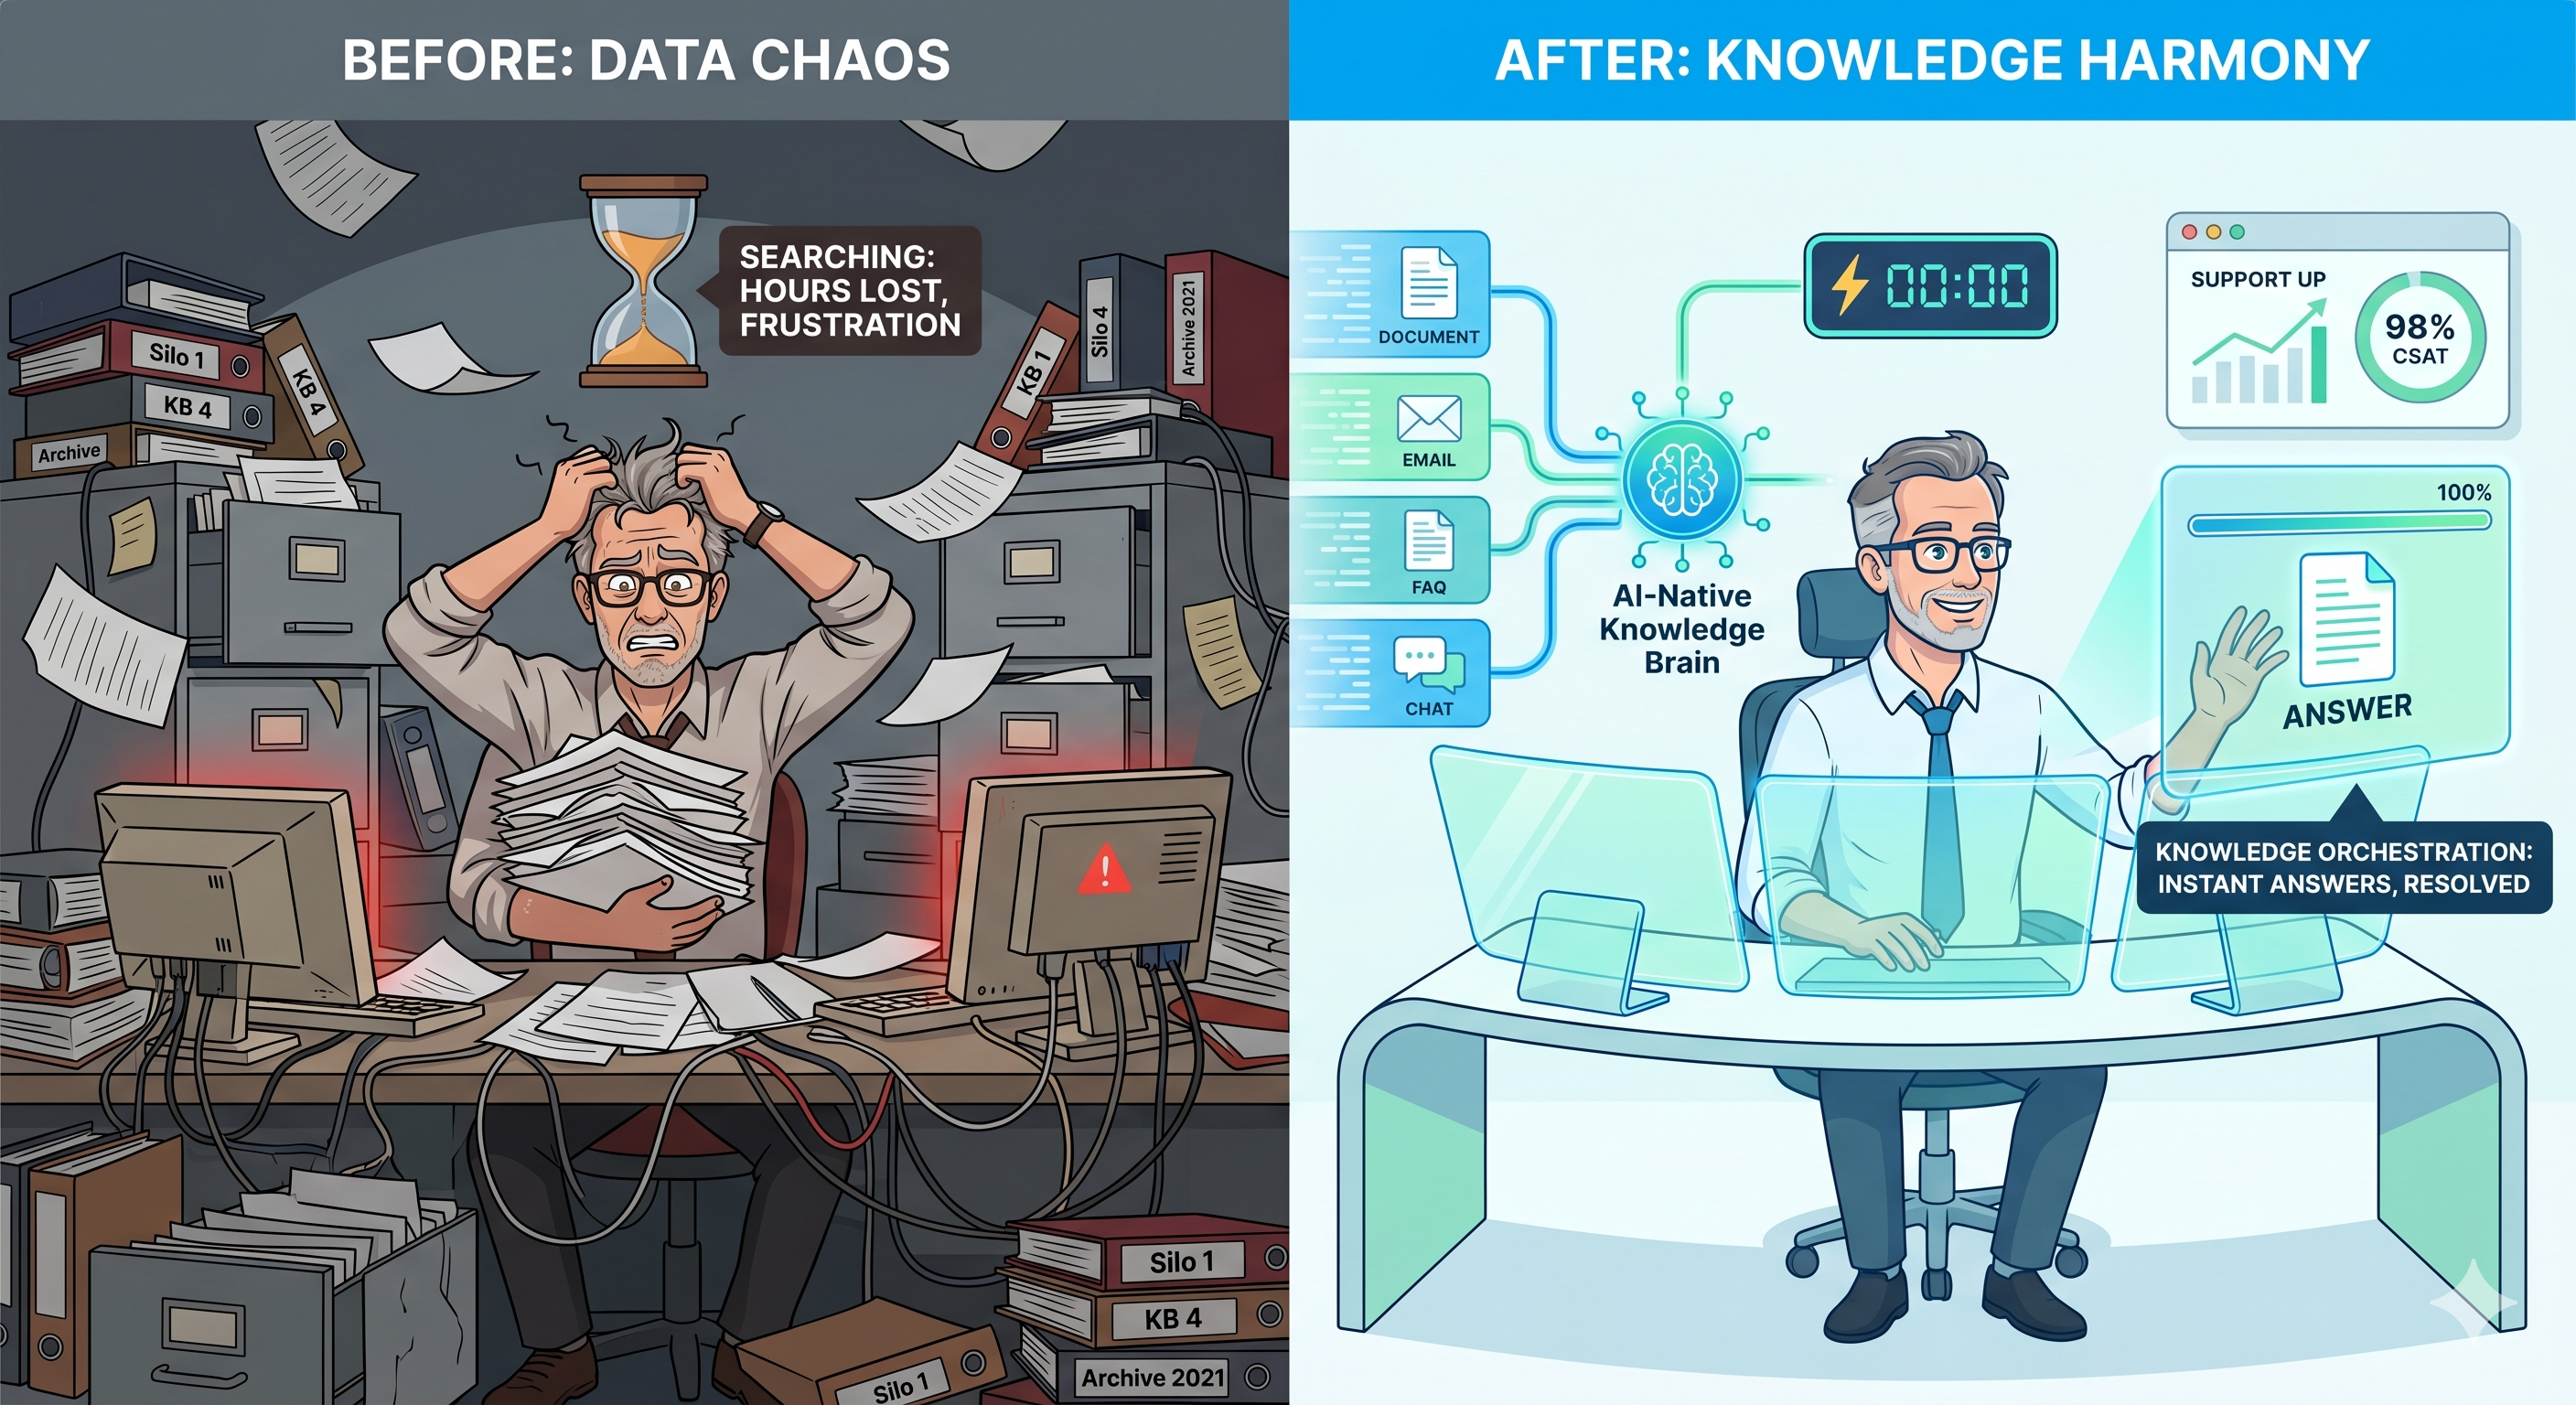
Side-by-side illustration contrasting 'Before: Data Chaos' — a frustrated worker buried in paperwork and silos — with 'After: Knowledge Harmony' — a calm worker using an AI-Native Knowledge Brain that unifies documents, email, FAQ, and chat into instant answers

AI-Native Knowledge Orchestration: Cut Search Time, Raise Support Accuracy, and Move Faster

How enterprise knowledge orchestration unifies fragmented content across Salesforce, SAP, Confluence, and email to improve search, support, and productivity.
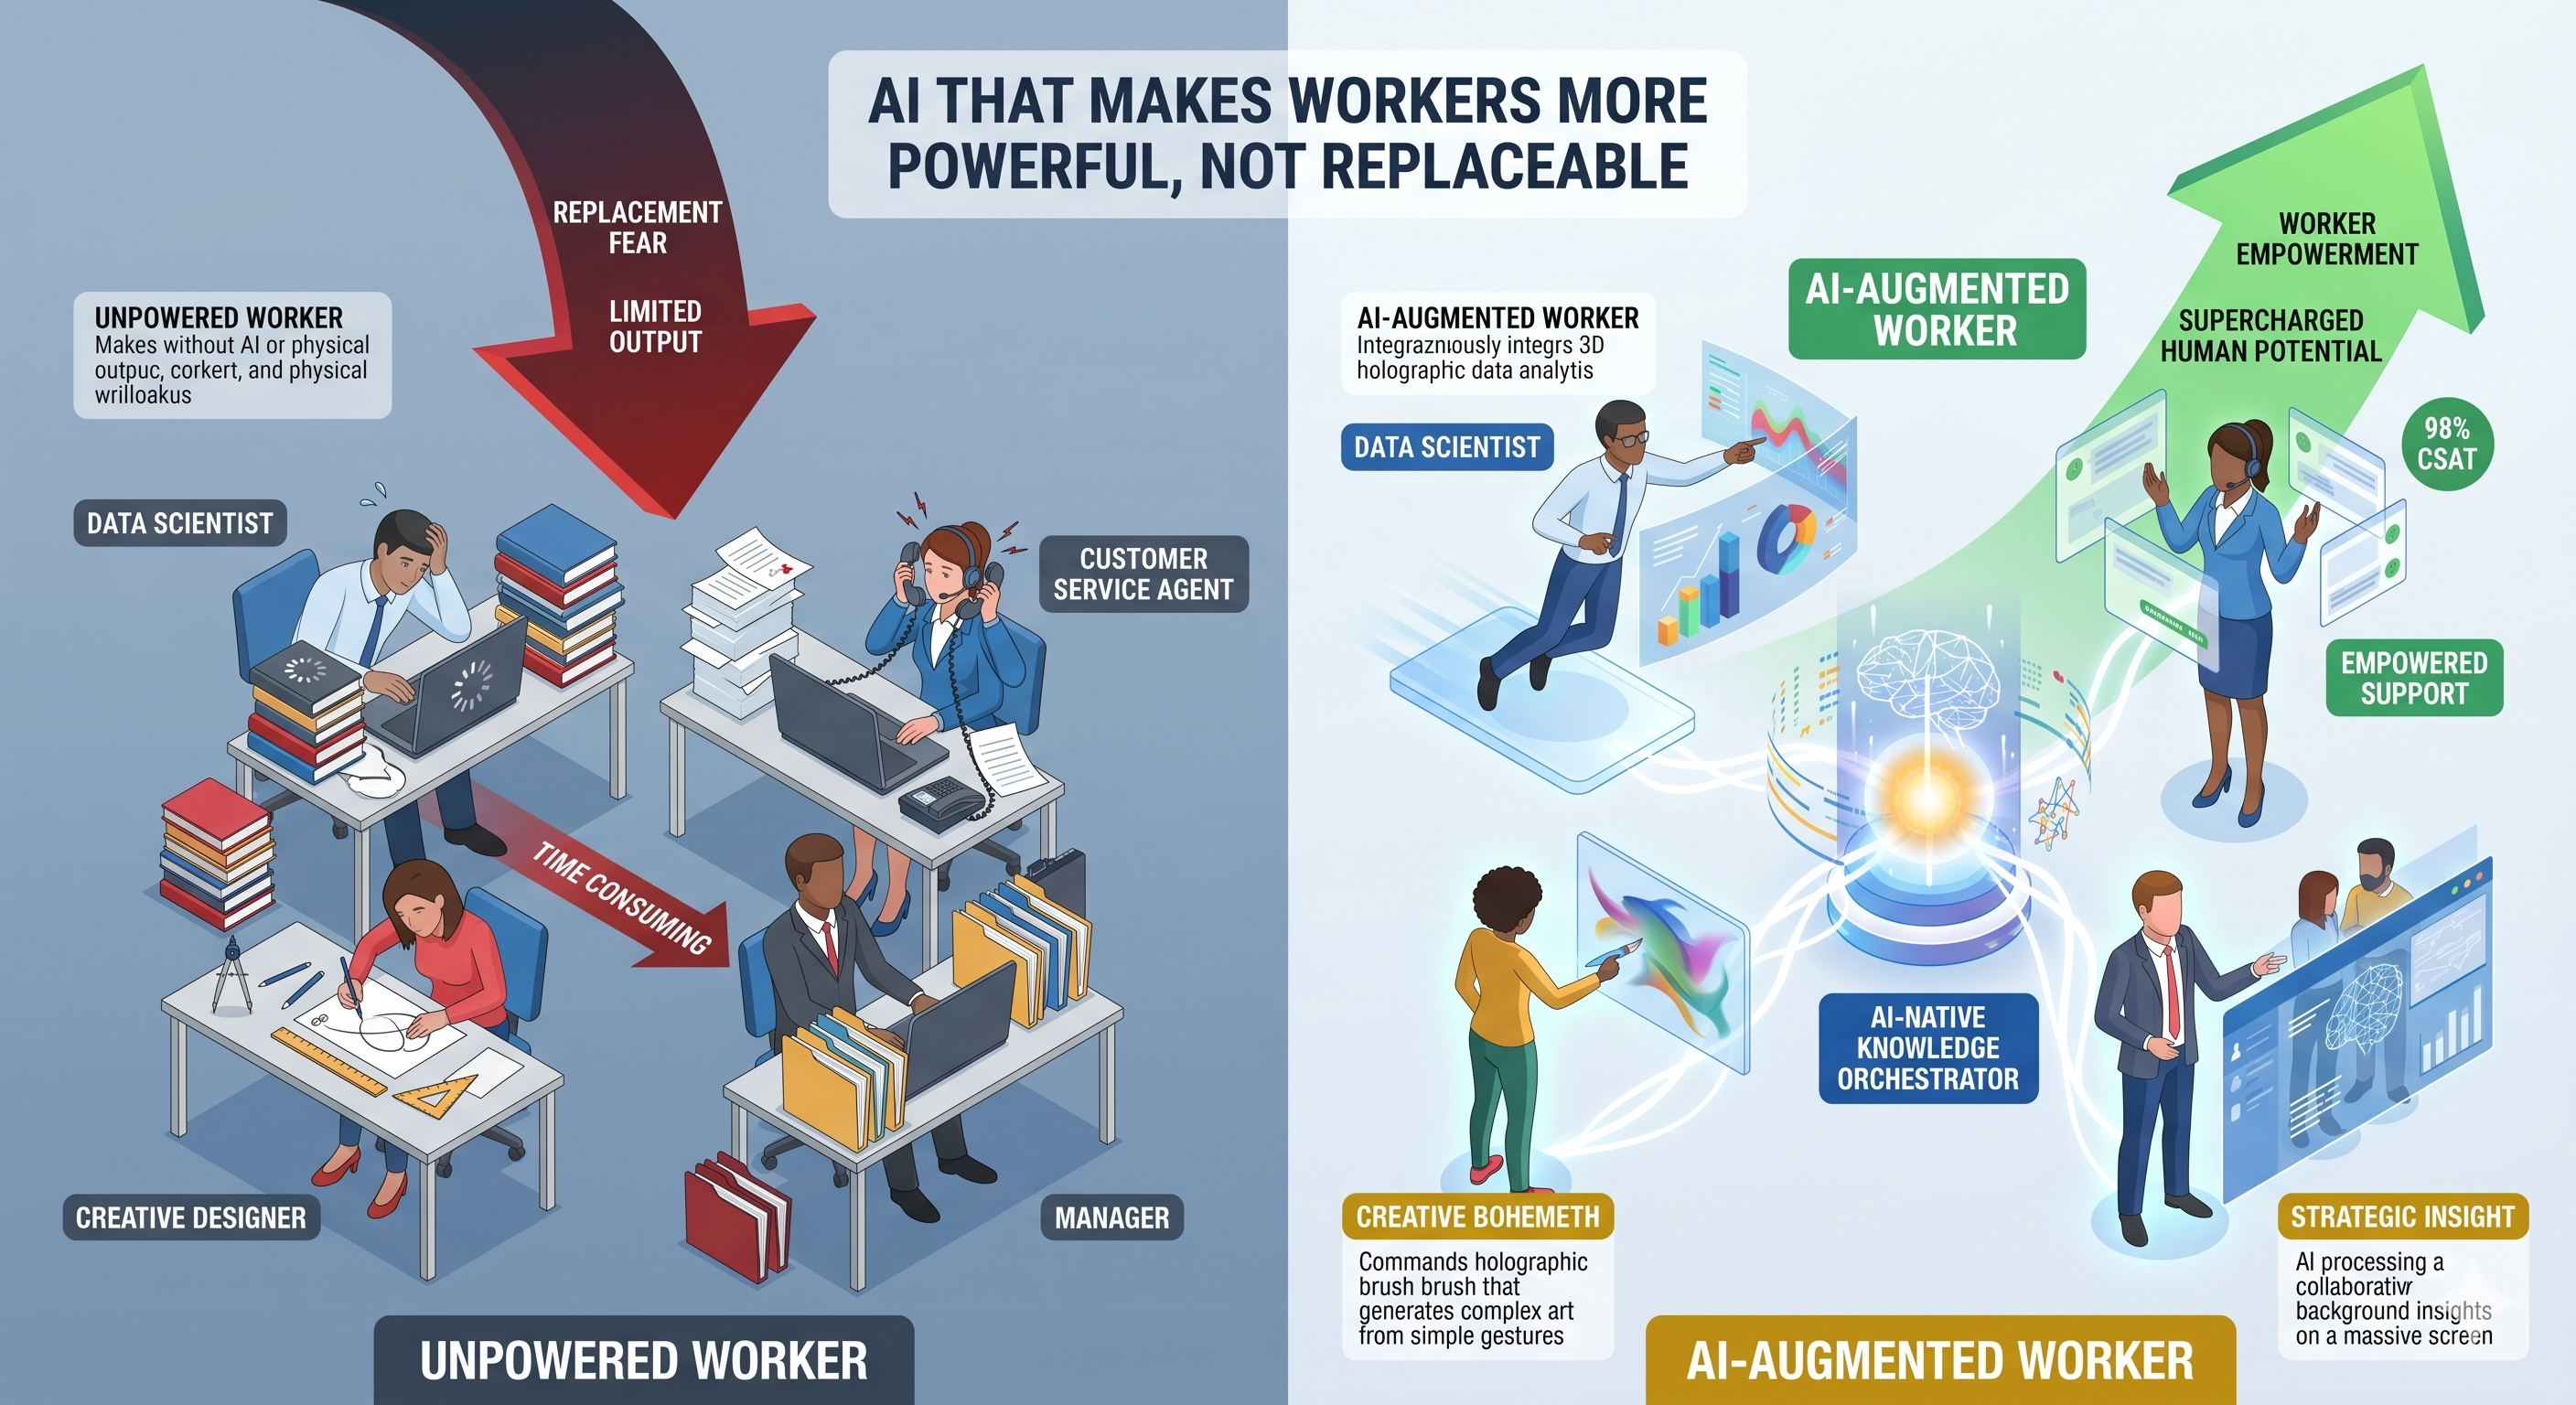
Side-by-side illustration contrasting an 'Unpowered Worker' panel — overwhelmed data scientist, customer service agent, creative designer, and manager buried in books and folders — with an 'AI-Augmented Worker' panel where the same roles are supercharged by an AI-Native Knowledge Orchestrator, with a green arrow showing worker empowerment

AI That Makes Workers More Powerful — Not Replaceable

Enterprise AI should 10x worker productivity and drive business growth, not eliminate jobs.